[ Set Up the Docking Project and Receptor | Preparing a Table with Peptide Sequences | Sequence Format Guide | Importing Sequences (Optional) | Docking a Peptide Table ]
|Video Example|
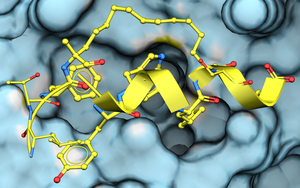 Peptide docking uses a sequence table and a prepared receptor docking project. Prepare the receptor, enter or import the peptide sequences, and then run Docking/Dock Peptide Table.
- Setup the protein receptor the same way you would for small molecule docking.
- Prepare a table of peptide sequences as described below.
To create a table for peptide sequences, follow these steps:
- Go to File > New and select the Table tab.
- Choose one string column and set the number of rows based on how many peptides you wish to dock.
- A new table will appear in the GUI.
- Rename the column containing the sequence to 'sequence' .
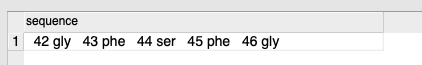
- Enter your peptide sequences in the format shown below:
[ Standard and Advanced Numbering | Specialized Bonds and Cyclization | Crosslinks and Modifiers | Terminal Designations | Preparing Extended Sequence Syntax for Unusual Amino Acids ]
Before defining sequences, check icmff.res in $ICMHOME (distribution directory) to see which residue types ICM supports. All defined residues are stored in the icmff.res file in the ICM distribution directory.
It is a text file so you can view it in a text editor or grep it. Example to search for ornithine grep ornithine icmff.res and you will see the code is 'orn'
- 3-Letter Codes:
gly ala ser pro tyr his - Advanced Notation: (Includes numbering, N/C-terminals, and D-amino acids)
0 nter 1 gly 2 ala 2A Dglu 4 asp cooh
- Disulfide Syntax: Use numerical markers in parentheses. Multiple disulfides can be encoded as (1), (2), etc.
acet ala cys(1) ala ala cys(1) ala conh - N-term to C-term Cycles: Use special "virtual" residues:
nvtr ala ala ala ala cvtr
Use curly braces {} for crosslinks or unusual modifications.
- Side-chain Crosslink: The 'Xa' stands for crosslink 'a' replacing an atom (e.g., Nz of lysine).
acet ala lys{nz_Xa} ala ala ala ala ala gln{he22_Xa} conh - Unusual Residues:
aba{hg1_C} ser{hg_C(=O)C)}See the unusual amino acid section below for more information.
Note: Modifiers cannot be applied to the backbone (C, Calpha, and N atoms). Hydrogen and side-chain atoms are acceptable.The terminal amide has to be preserved as backbone but you can create terminal amide to side-chain crosslink via a terminal ‘residue’
e.g.
… lys{ce_Xa} …. trp cmet{hm1_Xa}
| Terminal Type | ICM Residue Code |
|---|---|
| C-terminal amide | conh |
| N-terminal charged amine | nh3+ |
| N-terminal neutral amine | nter |
Example Input File Sequence:
nh3+ nle ala ala ala ala conh
- Automated Processing: You do not need to manually create new entries in the
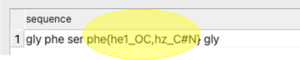
icmff.reslibrary for all unusual amino acids. ICM understands extended sequence syntax, defining unusual amino acids as modifications of natural ones. For example, 3-methoxy, 4-cyano phenylalanine is encoded as:
phe{he1_OC,hz_C#N}You can enter this text in the table to dock as shown below. - Generate Sequence Syntax for Unusual Amino Acid The
mol2modres.icmscript (included in$ICMHOME/bin) processes your monomer database to automatically prepare the residue definition strings. - SMILES Residue Modifiers: Prepare a sdf file of your unusual amino acids (remember to include chirality) and then run the script to output either an
.sdfor.csvfile. If a particular row cannot be converted, the resulting value will be left empty:
$ICMHOME/icm64 $ICMHOME/bin/mol2modres.icm unususal_amino_acid_monomers.sdf output=result.sdfYou will see a new column with the code for your amino acid which you can then copy and paste into your sequence for docking.
- You can import a table from an Excel or CSV file. Make sure that the column containing the sequence is labeled 'sequence'.
- If you have a peptide loaded from a PDB file, extract its sequence:
- Right-click on the peptide.
- Select>Extract Sequences to Table.
[ Start Docking | Adjusting Docking Parameters (Optional) | Restraining or Biasing the Peptide Structure ]
- `docking-start{Set up} the receptor as for small-molecule docking.
- Go to Docking > Dock Peptide Table.
- Click OK to use the default docking settings.
- To run from the command line prepare the input sequence as a sequence.se file and use _dockScan script.
- If you uncheck "dock immediately," you can modify settings before docking.
- Use the table side panel to adjust:
- Thoroughness
- Number of conformations
You can restrain or bias the ligand towards a specific secondary structure. To do this, define each residue with one of the following secondary structure types:
- H - Alpha helix
- G - 3/10 helix
- I - Pi helix
- E - Beta strand
- B - Beta-bridge
- _ - Undefined
- C - Coil